 Skip to content
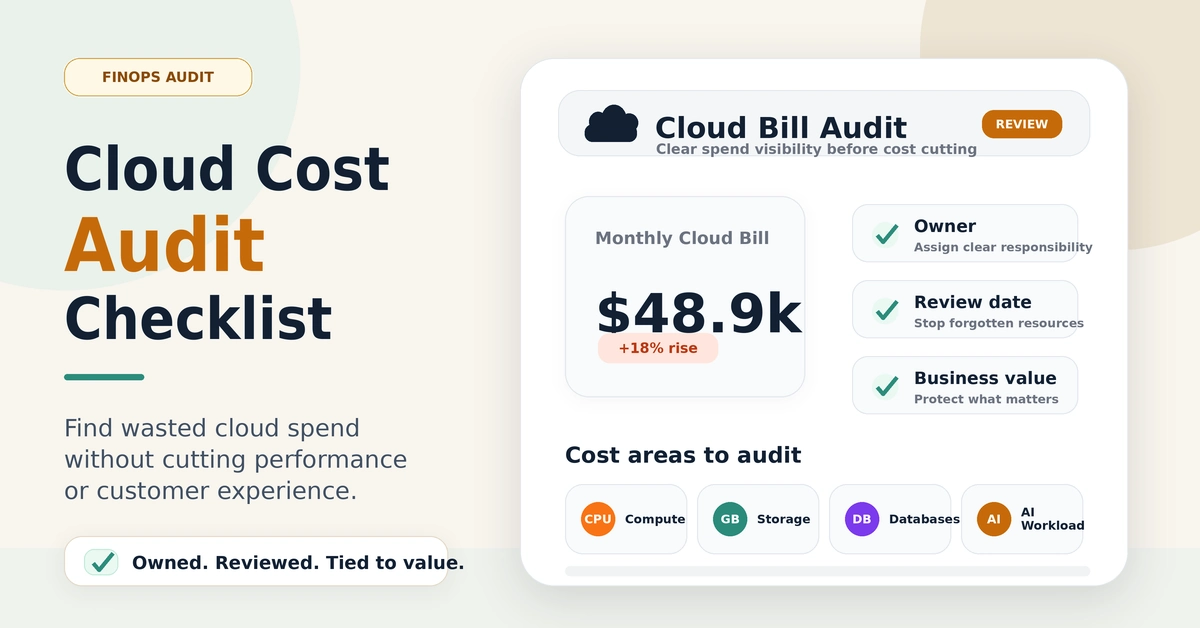
A cloud bill rarely becomes expensive because of one dramatic mistake. More often, cost grows through dozens of small decisions that were reasonable at the time and never reviewed again.
A test server stays online after a project ends. A database is sized for peak traffic that never arrives. Logs are kept longer than needed. A GPU workload becomes permanent after an experiment. A staging environment runs all night even though nobody uses it outside business hours.
This cloud cost audit checklist is designed for finance, engineering, IT, and operations teams that want to reduce waste without damaging performance, security, backups, or customer experience.
The goal is not to make the cloud bill as small as possible. The goal is to make every meaningful cost visible, owned, reviewed, and tied to business value.
Start With Visibility Before Optimization
The biggest cloud cost problem is often not overspending. It is not knowing what the spending supports.
If resources are not tagged correctly, finance may see a large bill without knowing which team, customer, product, environment, or experiment created it. Engineering may know the infrastructure but not the financial impact. Leadership may see volatility without a clear explanation.
Before cutting anything, make sure major resources have:
- a clear owner
- an environment label such as production, staging, or development
- a cost center or team
- a business purpose
- a review date
If nobody can explain what a resource does, that does not mean it should be deleted immediately. It means it should be investigated.

Cloud Cost Audit Checklist
Use this table as the first pass through your environment.
| Cost Area | What to Check |
|---|---|
| Compute | Idle instances, oversized virtual machines, always-on test environments, unused containers, temporary resources that were never removed |
| Storage | Old snapshots, unattached volumes, duplicate backups, object storage with no lifecycle rules, long retention periods |
| Databases | Oversized managed databases, unused replicas, old test databases, excessive backup retention |
| Data transfer | Cross-region traffic, internet egress, cloud-to-cloud transfer, analytics exports, unnecessary replication |
| AI workloads | Idle GPUs, unused notebooks, inactive inference endpoints, vector databases, experiments without budget limits |
| Logs and monitoring | Verbose logs, duplicate tools, unused dashboards, high-cardinality metrics, retention that exceeds operational need |
| Commitments | Reserved instances, savings plans, committed-use discounts, contracts that no longer match actual usage |
| SaaS and add-ons | Inactive users, duplicate services, unused cloud marketplace products, forgotten integrations |
| Ownership | Resources with no owner, no cost center, no project label, or no review date |
| Budget controls | Missing alerts, ignored thresholds, accounts with no spend owner, projects with no monthly budget |
Review Compute First, but Do Not Delete First
Compute is usually the easiest category to review because usage data is visible and many workloads are easy to classify.
Look for:
- virtual machines with consistently low CPU and memory usage
- development and staging environments that run 24 hours a day
- old instances created for migrations, demos, or one-time projects
- clusters with more capacity than current workloads require
- containers or serverless workloads with unexpected idle cost
The safest workflow is simple. Identify the resource, confirm the owner, verify the business purpose, and then decide whether to resize, schedule, consolidate, or remove it.
Do not delete production resources because a chart looks underused for one week. Capacity may exist for reliability, failover, seasonal demand, or planned growth.
Storage Waste Is Quiet and Persistent
Storage rarely causes an obvious operational problem, which is why waste can survive for years.
Separate stored data into three groups:
- data needed for active operations
- data needed for backup, compliance, or recovery
- data with no clear owner or retention reason
The third group deserves review.
Backups should never be removed casually. Every backup policy should answer four questions:
- What is being protected?
- How long must it be retained?
- Who owns the recovery requirement?
- Has restoration actually been tested?
Untested backups can create the worst of both worlds. The company pays for storage but still has no confidence that recovery will work.

Audit Databases Carefully
Databases are expensive and risky to change without context.
Check:
- instance size compared with real CPU, memory, storage, and connection usage
- read replicas that no longer support a real workload
- old test databases
- backup retention
- high availability settings that may be justified for production but unnecessary for non-production
A database that looks oversized may be carrying reliability headroom for traffic spikes. Do not resize it until performance and recovery requirements are understood.
Data Transfer Can Hide in Architecture
Teams often focus on compute and storage while missing data movement.
Review:
- cross-region traffic
- cross-zone architecture where charges apply
- internet egress
- data copied repeatedly between cloud platforms
- large analytics exports
- replication that no longer serves a business need
Architecture can be technically correct and still create unnecessary transfer cost. The right answer is not always to move data. Latency, resilience, compliance, and data residency may justify the current design.
AI Workloads Need Their Own Cost Controls
AI workloads can make cloud costs move faster because high-end compute, vector storage, model endpoints, and experimentation are easy to scale before the business case is clear.
Review:
- GPU jobs that remain allocated when idle
- development notebooks left running
- inference endpoints with low traffic
- vector databases with uncontrolled growth
- large prompt, output, and log retention
- training and fine-tuning jobs with no cost ceiling
Every significant AI workload should have an owner, a budget, a success metric, a review date, and a shutdown rule for experiments that fail to create value.
Logging and Monitoring Can Become a Major Bill
Observability is essential, but collecting everything forever is not a strategy.
Check:
- log retention by environment
- duplicate monitoring platforms
- high-volume debug logs in production
- metrics that nobody uses
- dashboards with no active owner
Security and incident-response requirements may justify long retention for some data. The goal is to match retention to a real operational or compliance need instead of keeping all telemetry indefinitely.
Review Commitments Before Buying More Discounts
Reserved capacity and committed-use discounts can reduce cost, but only when the usage pattern is stable enough to justify the commitment.
Before purchasing more commitments, check whether existing reservations or savings plans are fully used. A discounted resource that the company no longer needs is still waste.
This is where finance and engineering need to work together. Finance understands commitment exposure. Engineering understands which workloads are stable enough to commit.
Use a 7-Day Cloud Cost Cleanup Plan
A first audit does not need to take months.
Day 1: Identify the top cost drivers
Export the latest 30 to 90 days of billing data. Rank services, accounts, projects, regions, and resource groups by cost.
Day 2: Assign owners
Find the owners of the most expensive workloads. Mark unowned resources for investigation.
Day 3: Review non-production environments
Check development, staging, QA, demo, and temporary workloads for scheduling or downsizing opportunities.
Day 4: Review storage, backups, and logs
Check snapshots, unattached volumes, object storage, retention rules, and observability data.
Day 5: Review databases and managed services
Look for oversized databases, old test systems, unnecessary replicas, and expensive managed features that are no longer needed.
Day 6: Review AI and analytics workloads
Check GPU utilization, inference endpoints, notebooks, vector databases, data pipelines, and experiments.
Day 7: Create a recurring review
Set a monthly cost review involving engineering, finance, and the relevant business owners.
The first audit finds waste. The recurring review prevents it from returning.
What Not to Cut
Cloud cost optimization becomes dangerous when teams optimize cost without understanding risk.
Do not cut:
- backups without confirming recovery requirements
- database capacity without checking performance
- monitoring that is required for security or incident response
- redundancy that protects customer-facing availability
- regional architecture required for latency or data residency
- security controls simply because they appear expensive
Cost optimization means spending more intelligently, not spending as little as possible.
Build Governance So Waste Does Not Return
A one-time cleanup is useful, but it will not fix a weak operating model.
New workloads should have:
- an owner
- a budget
- an environment label
- a review date
- a business purpose
Temporary environments should have expiration dates. High-cost workloads should have budget alerts. Teams should review major cost changes regularly rather than waiting for finance to raise an alarm.
This is where FinOps becomes useful. FinOps gives finance, engineering, and business teams a shared way to understand cloud cost and value.
For provider-specific best practices, see the official cost optimization guidance from AWS, Microsoft Azure, and Google Cloud.
For more on long-term cloud governance, read How Poor Cloud Governance Leads to Massive Cost Overruns.

How to Know the Audit Worked
A successful audit should make the next bill easier to explain.
After the review, the team should know:
- the largest cost drivers
- which team owns each major workload
- which costs support production, development, experiments, or abandoned work
- which resources are candidates for optimization
- which alerts will warn the team before unexpected spend becomes a problem
Short-term savings matter, but clarity matters too. If the company saves money this month but still cannot explain next month’s bill, the audit is incomplete.
Final Cloud Cost Audit Rule
Do not wait until the bill becomes painful.
Start with the largest cost drivers. Assign ownership. Review non-production environments. Check storage and databases carefully. Put specific controls around AI workloads. Then turn the audit into a monthly operating habit.
A meaningful cloud cost should have a business purpose, an owner, a review date, and a measurable reason to exist. If one of those is missing, the resource deserves investigation.
For the wider picture beyond individual waste checks, review enterprise cloud spending risks, including ownership gaps, cost allocation, data transfer, commitments, observability and AI workload spend.
Author
Talha Qureshi is the founder and technology writer behind ITechTrove. He covers enterprise AI, cybersecurity, cloud infrastructure, B2B SaaS and emerging technology, focusing on practical guides, analysis and source-based reporting.

4 thoughts on “Cloud Cost Audit Checklist 2026 for Business Teams”